Showing posts with label private. Show all posts

Sunday, April 26, 2026

Logscale, dashboards, and DNS

Futurama gif with Fry screaming 'Fix It! Fix it! Fix it!' to Leela

Losgcale, or as it rather be called Crowdstrike Falcon Logscale (say that 3 times fast and Bettlejuice may show up), is a Security Information and Event Management(SIEM) made by Crowdstrike. In other words, it is a glorified log collector that allows you to ask questions, create alerts based on those questions, and present the answers in pretty dashboards and graphs. It is not the only game in town -- there are quite a few open source and commercial ones -- but it is the one we will be talking about today.

Dashboards, dashboards everywhere

A dashboard is way to show what the logs know in a pretty graphical way: most people just want to see what they need to care about the logs; they should not be forced to learn how to do that manually.

For instance, what if you want to show all the times the logs reported a specific event happened? Which event? I don't know. Maybe a failed sshsession. Since we will be using fake data, how about if we want to know if the logs detected the presence of The Dude? Maybe that would look like this in the logs:

<47>Apr 24 08:06:46 192.168.12.9 banana/error[285]: dude-abides=false
Note: This is being fed by my Python-based fake log generator script. So, it says whatever I want.

Now, let's create a quick dashboard since this article is not about how to create one. All we want it to do is to find The Dude and let us know when and where the presence of His Dudeness was detected. Where here would be the host name; it would be nice if we have the full name (balcony.example.org in this example), or FQDN. Technically logscale has a filed called host that should provide us that. Problem is that it gives us whatever the log had: if that was a hostname, we are good. But, what the host does not have the full name, instead just the balcony or IP (192.168.12.9) address? Losgcale provide the query command reverseDNS(), which can return the FQDN:

| reverseDNS(host, as="host_name")

With that, we could create a dashboard whose query looks like this:

tail(100)
| reverseDNS(host, as="host_name")
| has_dude := if(text:contains(string=msg, substring="dude-abides"), then="Yes", else="No")
| table([@timestamp, host_name, type, has_dude, msg])

Just before anyone asks, this is a very simple query because writing dashboards is not the topic of this article. All I want it to do is to get logs like this (one of them has a message body I saved from a real alert down to the IP address)

<63>Apr 24 08:06:41 192.16.94.101 tiktok/error[1197]: Did you see that?
<47>Apr 24 08:06:46 192.168.12.9 banana/error[285]: dude-abides=false
<66>Apr 24 08:06:47 192.168.55.85 tiktok/error[867]: right_droid=false
<1>Apr 24 08:06:48 192.16.55.6 unamed[1155]: Did you see that?
<8>Apr 24 08:06:50 192.168.12.137 rm/error[1733]: Cannot destroy all humans
<20>Apr 24 08:06:51 192.16.55.6 tiktok/error[121]: %RCMD-4-RSHPORTATTEMPT: Attempted to connect to RSHELL from 217.69.139.202
<45>Apr 24 08:06:52 192.168.55.85 tiktok[426]: right_droid=false

which have IP addresses for hostnames (note the IP range; it will be important later). The "job" of the query is to identify those logs containing dude-abides. To make it look pretty, we are using the function reverseDNS() to convert the IPs to FQDNs.

The output should look like a table with 4 columns (you can stretch the window to try to make table look pretty):

@timestamp host_name has_dude msg
2026-04-24 04:06:41.000 balcony.example.org No Did you see that?
2026-04-24 08:06:46.000 balcony.example.org Yes dude-abides=false
2026-04-24 04:06:47.000 saladbar.example.org No right-droid=false
2026-04-24 04:06:48.000 kitchen.example.org No Did you see that?
2026-04-24 04:06:50.000 bathroom.example.org No Cannot destroy all humans
2026-04-24 04:06:51.000 kitchen.example.org No %RCMD-4-RSHPORTATTEMPT: Attempted to connect to RSHELL from 217.69.139.202
2026-04-24 04:06:52.000 saladbar.example.org No right-droid=false
Note: The reason we have 000 in the end of the time (ex: 08:06:46.000) is that logscale can handle/expects/would like that to be in microseconds. When it does not get them, it makes microseconds = 000.

It is broken!

When we run it the dashboard, something goes wrong: where is the host_name?

Screen capture of the logscale dashboard we created (looks like the table above). The host_name column is missing

Here's a representation of the above in glorious ASCII):

@timestamp has_dude msg
2026-04-24 04:06:41.000 No Did you see that?
2026-04-24 08:06:46.000 Yes dude-abides=false
2026-04-24 04:06:47.000 No right-droid=false
2026-04-24 04:06:48.000 No Did you see that?
2026-04-24 04:06:50.000 No Cannot destroy all humans
2026-04-24 04:06:51.000 No %RCMD-4-RSHPORTATTEMPT: Attempted to connect to RSHELL from 217.69.139.202
2026-04-24 04:06:52.000 No right-droid=false

So, how to make it work? By default logscale uses the dns servers known by the host it is running on. In Linux they could be defined in resolv.conf (I am going to use dns1, dns2, and so on to define the dns servers instead of using IPs so it is easy to see them; this is getting long):

[banana@logscale-box ~]$ cat /etc/resolv.conf
# Generated by NetworkManager
search example.org
nameserver dns1
nameserver dns2
[banana@logscale-box ~]$

dns1 and dns2, being our internal dns servers, do know all of our hosts in the 192.168.xx.xx (technically I should represent that as 192.168.0.0/16) range, which is a private IP range

Note: Private IP Addresses are those defined by RFC 1918 to belong to one of the following ranges: 192.168.x.x, 10.x.x.x, and 172.16.x.x

It turns out by default (again that word) logscale will not convert IPs in the private IP address ranges, you have to force it to do so. And that is done using 3 environmental variables (I call them constants. but what do I know?) defined in /etc/logscale/humio.conf: RDNS_DEFAULT_SERVER, IP_FILTER_RDNS_SERVER, and IP_FILTER_RDNS:

RDNS_DEFAULT_SERVER
  • Defines the server used when no server is explicitly specified in the function call
  • Ex: RDNS_DEFAULT_SERVER=192.168.5.3
IP_FILTER_RDNS
  • For reverse DNS lookups in reserved IP addresses
  • Which IP addresses can be queried with rdns() and reverseDns()
  • Ex: IP_FILTER_RDNS=deny 10.0.5.0/24; allow all
    • Cannot query hosts in the 10.0.5.0/24 range
    • Can query reserved IP addresses that are in other ranges.
IP_FILTER_RDNS_SERVER
  • For RDNS server filtering
  • Only restricts which servers can be explicitly specified in rdns() or reverseDns() function calls
  • If RDNS_DEFAULT_SERVER is defined, include it
  • Ex: IP_FILTER_RDNS_SERVER=allow 192.168.7.1; deny all
    • Allows 192.168.7.1 (and 192.168.5.3) as rdns servers for reserved IP addresses

Since dns1 and dns2 can resolve the problem, all we would need to do is to add the following lines to /etc/logscale/humio.conf:

IP_FILTER_RDNS_SERVER=allow all
IP_FILTER_RDNS=allow all

The following screen capture does show hostnames under host_name; I just deleted them because I used real names. I will manually alter the file(!) to put mine later.

Screen capture of the logscale dashboard we created (looks like the table above). The host_name column is now visible

Variations on the theme

  1. What if I just want to only allow the use of dns2 for reverse dns?

    Edit IP_FILTER_RDNS_SERVER

    IP_FILTER_RDNS_SERVER=allow dns2; deny all
    then, optionally, edit the dashboard query
    | reverseDNS(host, as="host_name", server="dns2")
  2. What if I want to only use a dns3 for reverse dns, but not define it in resolv.conf?

    Edit humio.conf

    RDNS_DEFAULT_SERVER=dns3
    IP_FILTER_RDNS=allow all
    IP_FILTER_RDNS_SERVER=allow dns3; deny all
    then, optionally, edit the dashboard query
    | reverseDNS(host, as="host_name", server="dns3")

More Complex Examples

What if I want to add google's dns server to resolv.conf as failover in case my DNS servers are both down?

[banana@logscale-box ~]$ cat /etc/resolv.conf
# Generated by NetworkManager
search example.org
nameserver dns1
nameserver dns2
nameserver 8.8.8.8
[banana@logscale-box ~]$

It depeneds on the other settings:

  1. If you do not add the IP_FILTER_RDNS*humio.conf? Logscale will be in default mode and never try to resolve private IP addresses. And that is what started the events that lead to this article.
  2. If you set humio.conf as in the original example,
    IP_FILTER_RDNS=allow all
    IP_FILTER_RDNS_SERVER=allow all
    
    and do not specify a dns server in the dashboard query as in the original case
    | reverseDNS(host, as="host_name")
    Logscale may try to that for the private IPs, which will not work but now oyu are telling google, and possibly others who are listening, which private IPs you use. Don't do this!
  3. If you set humio.conf as in the original example,
    IP_FILTER_RDNS=allow all
    IP_FILTER_RDNS_SERVER=allow all
    
    and specify a dns server in the dashboard query
    | reverseDNS(host, as="host_name", server="dns2")
    Logscale will gracefully not show host_names when dns2 is down, and will not query google's.
  4. If you set humio.conf specifically telling which dns servers to use. This is better than the previous solution
    IP_FILTER_RDNS=allow all
    IP_FILTER_RDNS_SERVER=allow dns1; allow dns2; deny all
    
    and do not specify a dns server in the dashboard query as in the original case
    | reverseDNS(host, as="host_name")
    Logscale will only show host_names when either dns1 or dns2 is up, and will never try to query google's. This is the best because you are limiting which dns servers to use in one single location (humio.conf) instead of possibly filtering every single dahsboard. If you need to have dashboards quering specific dns servers, add them to the humio.conf file as above and then use the specific one where needed. This add a second layer of protection.

Saturday, November 18, 2023

Online subscriptions: Giveth and Taketh Away

Like many, I too have a gmail account. And I have used it to buy magazines, tv shows, and even subscriptions. My reason is the same as everyone else: it is convenient. Recently I received an email stating

Here is the text version, so people can translate to their language or jut be able to read it without having to rely on the image:

Since 2020, new purchases of magazines have not been available in Google News and very few users now regularly access their magazine subscriptions. We wanted to inform you that support for magazine content in Google News is being discontinued beginning on December 18, 2023, which means access from Google News apps or news.google.com to the library of magazines you previously purchased or subscribed to will be removed. To continue to access previously purchased magazine content, you must export and save each purchased issue before December 18, 2023.

Claiming this to be a security or even privacy topic may sound like a bit of a stretch, but hear me out. When you buy a TV show, movie, or even magazine subscription through Google, Apple, Amazon, Barnes & Noble, or whoever, unless you can download that to your computer and view it without needing to use their website or app, you may lose access to them for different reasons:

Technical issues.

People have reported ebooks purchases they made and downloaded to their book reader -- usually a phone app or Kindle -- one day are no longer in their devices. Or said books are no longer even listed in their accounts. Or, even when said books are in their devices, pages are/became missing. Contacting the publisher (or should we call them streaming providers as they may only be licensing the sale/distribution of the product?) can lead to hours if not months of frustration; they may be equally baffled for the reason of these problems.

This also frustrates authors, whose present and future earnings is directly related to the popularity of their work: imagine if one of your books was #1 bestseller and then because of a computer glitch with the streaming provider it cannot be easily found, downgrading it to #150. This have happened already.

The Wikipedia Effect

Wikipedia is a living document: people are always editing and improving on its contents. So, what you have read last month may have been disputed and edited out of it. That leads to arguments that it should not be quoted as reference source. Some authors and producers may feel the initial version of their book or movie did not portray the story the way they intended and would love to be able to come back, months or years after publication, and change it. George Lucas is the posterchild of this.

With streaming that no longer means a new release: all the old versions can be now updated just like a computer program. I myself have seen shows whose opening credits for specific episodes have changed at least 3 times; the latest of which added hints to events in the episode which really do not add value to it. Bottom line is what you bought last year may no longer be what you have. Is this good or bad? That is up to you. In my opinion while there is a benefit for textbooks and study guides, when we are talking about a work of fiction or even a technical paper, that removes the power from you the buyer to decide which version you have. I am glad I am still able to see the original Star Wars trilogy without the cgi "enhancements" added later.

Licensing issues

Let me cut to the chase: you do not own what you paid for. According to the Amazon's Conditions of Use (not singling them out but it was the one I could easily found),

COPYRIGHT
All content included in or made available through any Amazon Service, such as text, graphics, logos, button icons, images, audio clips, digital downloads, data compilations, and software is the property of Amazon or its content suppliers and protected by United States and international copyright laws. The compilation of all content included in or made available through any Amazon Service is the exclusive property of Amazon and protected by U.S. and international copyright laws.

The part I highlighted (boldfaced?) is the one we want to look at. All those Kindle books and movies and music you bought at Amazon Prime belong to Amazon or whoever they licensed it from. You only paid a license to access them, and contrary to social media sites and even companies you work at this license is not perpetual. There has been cases where, for instance, Kindle owners found books they purchased were removed from their accounts. And it does not end there: the Amazon Services Terms of Use states that this license can be revoked. While its words claims that termination only happens if they decide your are not in strict compliance with the agreement, they do reserve the right to decide if that is the case.

How does that affect privacy?

Some books or movies were removed from streaming sites because they were considered inappropriate; that in itself can mean many things including not politically acceptable. Your purchase/subscription records are in possession of these streaming providers. Depending on the location of residence, what can possibly be personal information -- they can be used to infer religious beliefs, sexual orientation, and so on -- is sold to other merchants, which will certainly use this data to create a profile on you (called an avatar) to better market to you be it by ads on free phone apps or even plain old emails. Others such as government and more criminal-minded organizations can also acquire the data for their own purposes.

How to minimize personal data exposure?

If you like a movie or a book, why not buy the movie on DVD/Blueray or the book either printed or at least as a PDF? At the very least now you own it in a way they cannot remove your access to it. You can find privacy-respecting DPF readers for most phones and computers. You can still convert the movie available in some electronic form so you can watch it without worrying about damaging the disk. There may be legality issues which are beyond this post but the technology is there. As a bonus, you do not have to worry about the content of your purchase changing from the version you paid for.

Wednesday, November 17, 2021

German Federal Office for Information Security leaks private encryption key

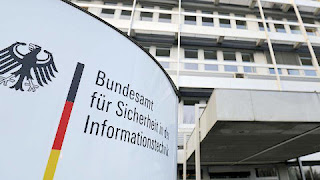
BSI office in Bonn. Photo by Oliver Berg, DPA

The Bundesamt für Sicherheit in der Informationstechnik (German Federal Office for Information Security) (BSI) is the German federal agency in charge of managing computer and communication security -- critical infrastructure protection, internet security, certification of security products -- for the German government. It also advises manufacturers, distributors, and users on identifying and minimizing data security risks. Like many organizations, when the GDI needs to send or receive an encrypted email, it relies on the OpenPGP standard. It creates a public/private keypair and then shares the public key with anyone who wants to send a message. That not only allows senders to know only BSI can decrypt their messages but also verify it was indeed BSI who replied to it.

Early this month Golem.de reported that the BSI, when asked for the public key by someone who wanted to submit confidential information, accidentally sent the corresponding private key. Eventually this key was revoked and a new keypair was issued, but that happened only after Golem.de contacted the BSI.

Questions

  • How long has the BSI known of that data breach? Per GDPR's Article 33, a data breach should be reported to the nearest Data Protection Authority within 72 hours of the Data Controller, in this case the BSI, becoming aware of it.
  • How long did it take for its Data Privacy Officer (DPO) to inform the data subjects? Per the Golem.de article, the BSI kept using this key pair for months after the incident.
  • How many data subjects were affected by this data breach?
  • Has it immediately created a new keypair and let all those who rely on that know of the incident and receive the new public key? According to the Golem.de article, the BSI still used that keypair for months after the incident.
  • The BSI stated the key was password protected. One must assume the (accidental) recipient of this email had the password. However, we have no idea of the strength of password. Because of how the SMTP protocol works, there are many opportunities to get a copy of the email containing the encrypted key as attachment. And then, it becomes the classic password cracking routing in the comfort of your home.

Notes

While many are looking at this event from a security standpoint, this really should be seen from the privacy standpoint:

  • The impact on the privacy of those who have used this compromised key is yet to be understood. How much personal data has been exchanged using this very key under the assumption it was protected from prying eyes? This encryption key is probably only used to transmit sensitive data; once it is received, it is downloaded, extracted, decoded, and then acted upon. So, unless it is deleted, it is stored in encrypted format at the customer's and the BSI destination mail accounts. And it is possible that the mail transfer agents (MTA) that act as hops between them, storing and relying to the next hop, also keep a copy for a period of time.
  • While they probably did a Data Protection Impact Assessment (DPIA), one must assume this kind of data breach was not a possibility they considered. However, hindsight is always 20/20: it very easy to, after this breach is exposed, point fingers at them, but I would like to know any company which accounted for this in their risks from their accidental or unauthorized actions list before this incident.
  • Privacy by design is a lofty goal, but in reality it can never be fully achieved. Best we can do is take this as a teaching moment. For instance, we expect that the BSI will now implement a system in which private keys can be used but not directly accessed.

References